Deccan builds verifiable environments and data across RL, 3D and Robotics — the three areas you're building in. This package brings our work in all three into one place: each a self-contained delivery with its own deep-dive report, every sample leading with the numbers.
3
domains — RL · 3D · Robotics
Reinforcement learning
Three verifiable-RL gyms with scored rollouts, verifier evidence and per-failure analysis.
Reinforcement learning · SWEVerifiable RL
DeepSWE Bench
30%
frontier pass@5 (15/50) — every task in the 0–2/5 band
Ten long-horizon coding tasks mined from live private production codebases, authored via an LLM + human-in-the-loop pipeline and calibrated on a fixed harness — the reference solution scores 1.0, the empty submission 0.0.
pass@k scored10 tasksPHP · JS · TS · Python50 rolloutsreward-hacking audit: clean
Open the DeepSWE Bench report
Reinforcement learning · BrowserVerifiable RL
Browser Gyms
22%
frontier pass@5 (11/50); 4 of 10 tasks never passed
Ten cross-gym agent tasks across five simulated SaaS products — XSN, Xalendly, Xubspot, Xmail and Xira — each scored by atomic database-expectation verifiers after live browser execution.
pass@k scored10 cross-gym tasks5 SaaS gymsDB-expectation verifiers50 iterations
Live browser-agent run · Xira project-management gym
Reinforcement learning · TerminalVerifiable RL
Terminal-Bench 3
17%
GPT-5.6 Sol full-credit (8/48) — every task held ≤ 40%
Ten hard, reference-solvable tasks across five Terminal-Bench 3 categories — Security, Operations, Science, Software and ML — scored against GPT-5.6 Sol at pass@5, with Gemini 3.7 Flash and Hy3 run alongside as benchmarking arms.
10 tasks5 categories3 model arms196 rolloutsno reward hacking
Open the Terminal-Bench 3 report
3D
Verifiable 3D authoring, and 3D at industrial scale.
3D · Verifiable authoring environmentAgentic 3D · bpy
Blender bpy Agent Episodes
172
deterministic end-state checks against the saved .blend
A verifiable 3D-authoring environment: an agent writes Python (bpy) to build 3D scenes, and every episode is graded by an end-state verifier that re-opens the saved scene in a fresh Blender and renders it from the harness, not the agent.
end-state verifier33 check types265 tool calls5.2M verticesagentic + instruction→script
Harness render · muscle-coupe turntable
Harness render · starliner flythrough
Every check is a deterministic function of the saved .blend — renders and checks are produced by the harness, so the score can't be gamed by agent self-report.
Open the Blender catalogue
3D · Industrial CAD & fabricationReal-world dataset
Structural Steel Data Pack
6.8 TB
real US steel-detailing production data
A 6.8 TB structural-steel fabrication dataset — coordinated 3D models (STEP, IFC, Tekla), 2D shop drawings and CNC programs from live US fabrication work, all linked by piece mark: 3D model → drawing → machine code.
6.8 TB · 4.2M files17,410 3D models~2.9M 2D drawings~991K CNC programsSTEP · IFC · DWG · DXF · PDF
Interactive 3D · structural steel frame — drag to rotate
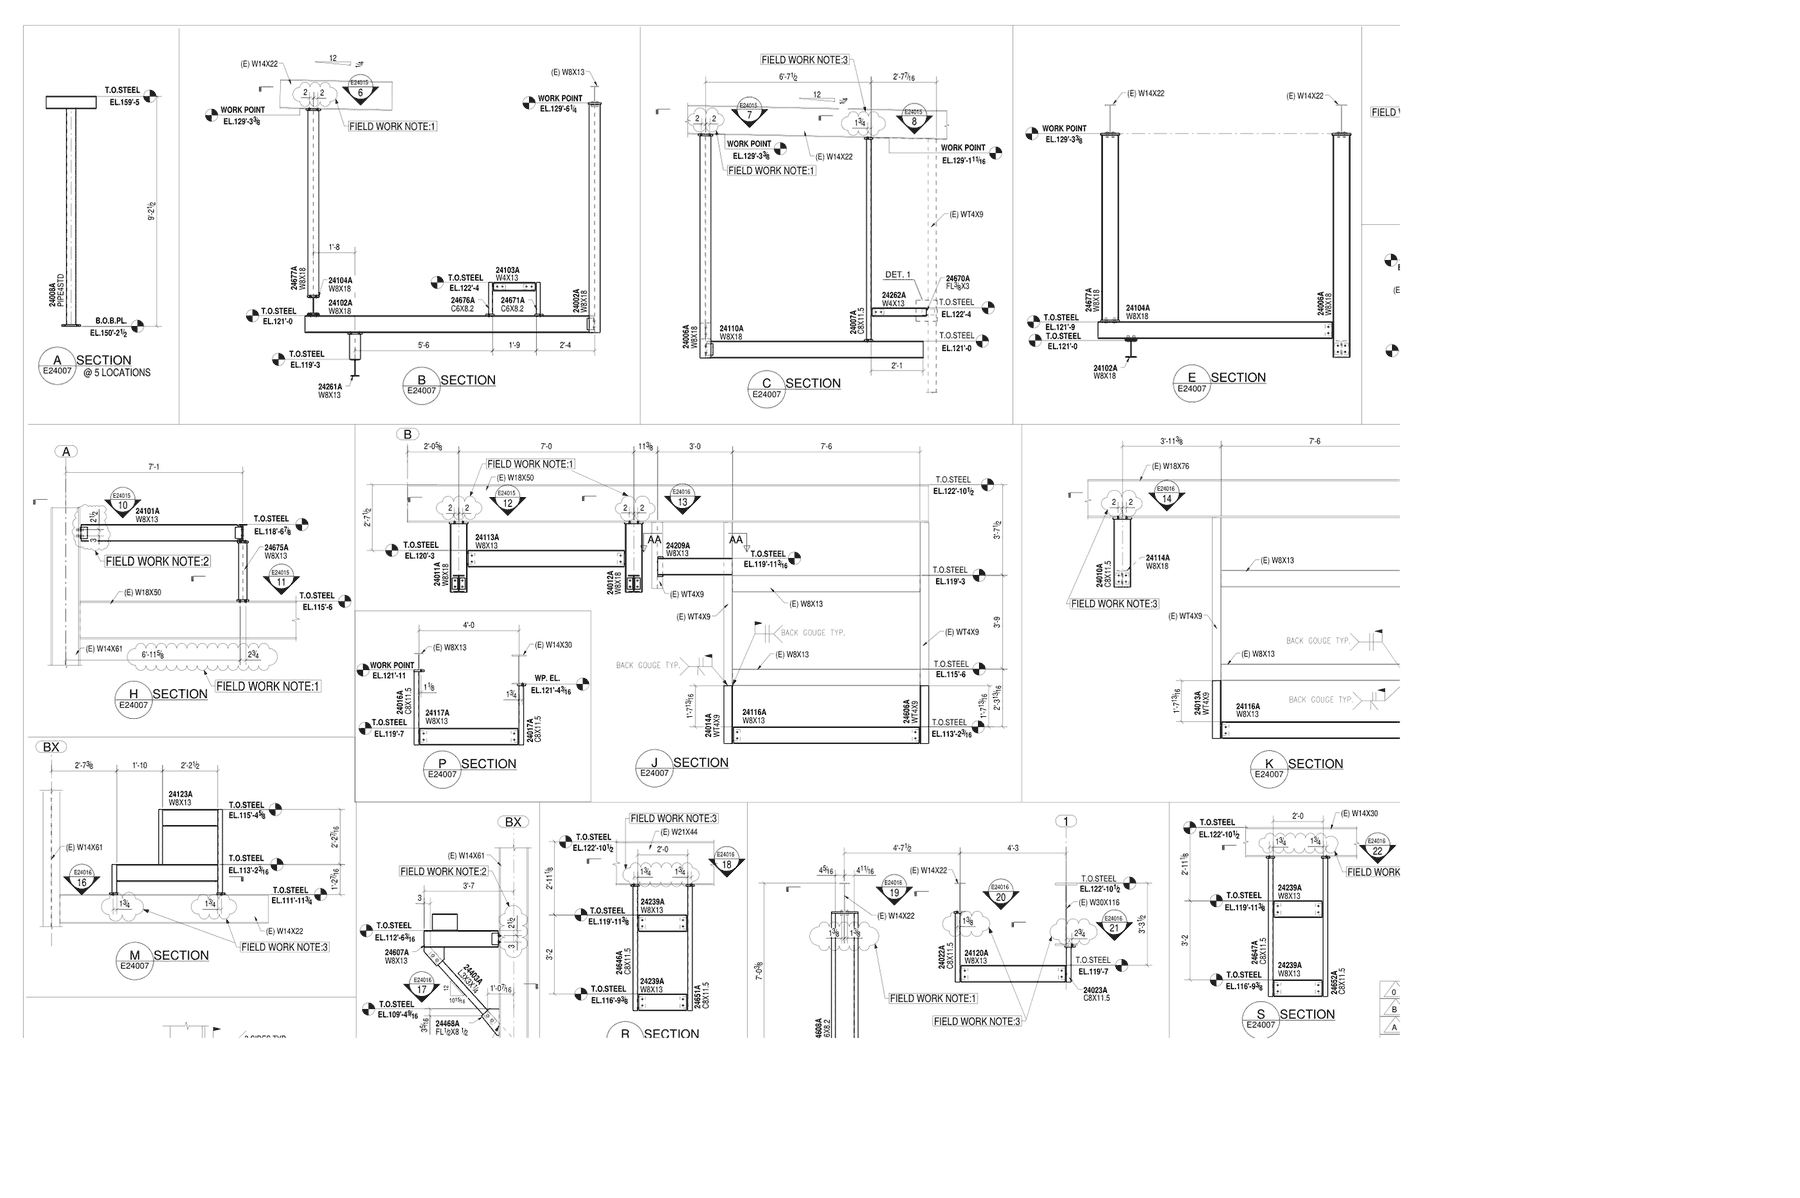
2D shop drawing — connection details
Robotics
A verified failure-and-recovery data engine, with live demonstrations.
Robotics · Failure-and-recovery engineIsaac Sim · LeRobot
FailRec — verified failure & recovery
5
verified failure-recovery dataset lines + custom builds
An engine that manufactures realistic robot-failure trajectories and provably-working recoveries in rich simulated scenes — then proves the data transfers. A standing supplier of on-demand failure-recovery data in LeRobot format, every recovery machine-verified to complete.
verified recoveriescause-tagged failuresrealism-calibratedtransfer-provenLeRobot format
Demo · front view — bimanual fruit-sort (Franka Panda)
Demo · top view — labeled-bin sort with recovery
Five dataset lines — Kitchen & Home, Tabletop, Articulated Objects, Industrial & Assembly, and Recovery-Manifold Packs — each a failure paired with a verified, executable recovery.
Talk to us about coverage & custom builds
Preview · in progress
An early probe into video → 3D floor-plan reconstruction — now scored against real ground truth by an LLM judge.
3D · Video → floor-plan reconstructionJudged vs. ground truth
Room Layout from a Video Flyby
10
model outputs scored against Zillow ground truth (Opus-5 judge, 0–100)
Given an egocentric video walkthrough, the agent must reconstruct a globally consistent 2D spatial layout. Because ground-truth layouts exist, you get deterministic rewards for topology, geometry and connectivity, which enables scalable RL and evaluation. Agents that succeed demonstrate long-horizon spatial reasoning and memory — key to embodied AI and robotics.
video → floor planZillow ground truthLLM-judge scored5-criteria rubric10 outputs
This single-property demo scores six models against Zillow’s ground-truth plan (LLM judge, Claude Opus 5; top output 80/100) — the ground-truth layouts are what make deterministic, scalable rewards possible.
Open the room-layout comparison
These span the stack you're building.
Across RL, 3D and Robotics we build and operate these environments and datasets at scale — with the same standard of verifiable grading, full evidence, and per-failure analysis you see in each report here.
We'd be glad to talk through scaled operations, custom environment and dataset builds, and OTS access for any of these lines — including custom robot embodiments, tasks and failure taxonomies through the FailRec engine.


